
dsh-voice-conversation
维护状态: 活跃redhunt07/dsh-voice-conversation
DSH的免提意大利语/英语语音对话:说话,暂停1.7秒并提交提示;回复后继续收听,带有内联聊天底座和可选的本地Whisper/Piper后端。
$ dsh plugin add dsh-voice-conversation3
星标
0
Fork
JavaScript
语言
MIT
许可证
2026-10-30
创建于
2026-11-01
最近推送
README
DSH Voice Conversation


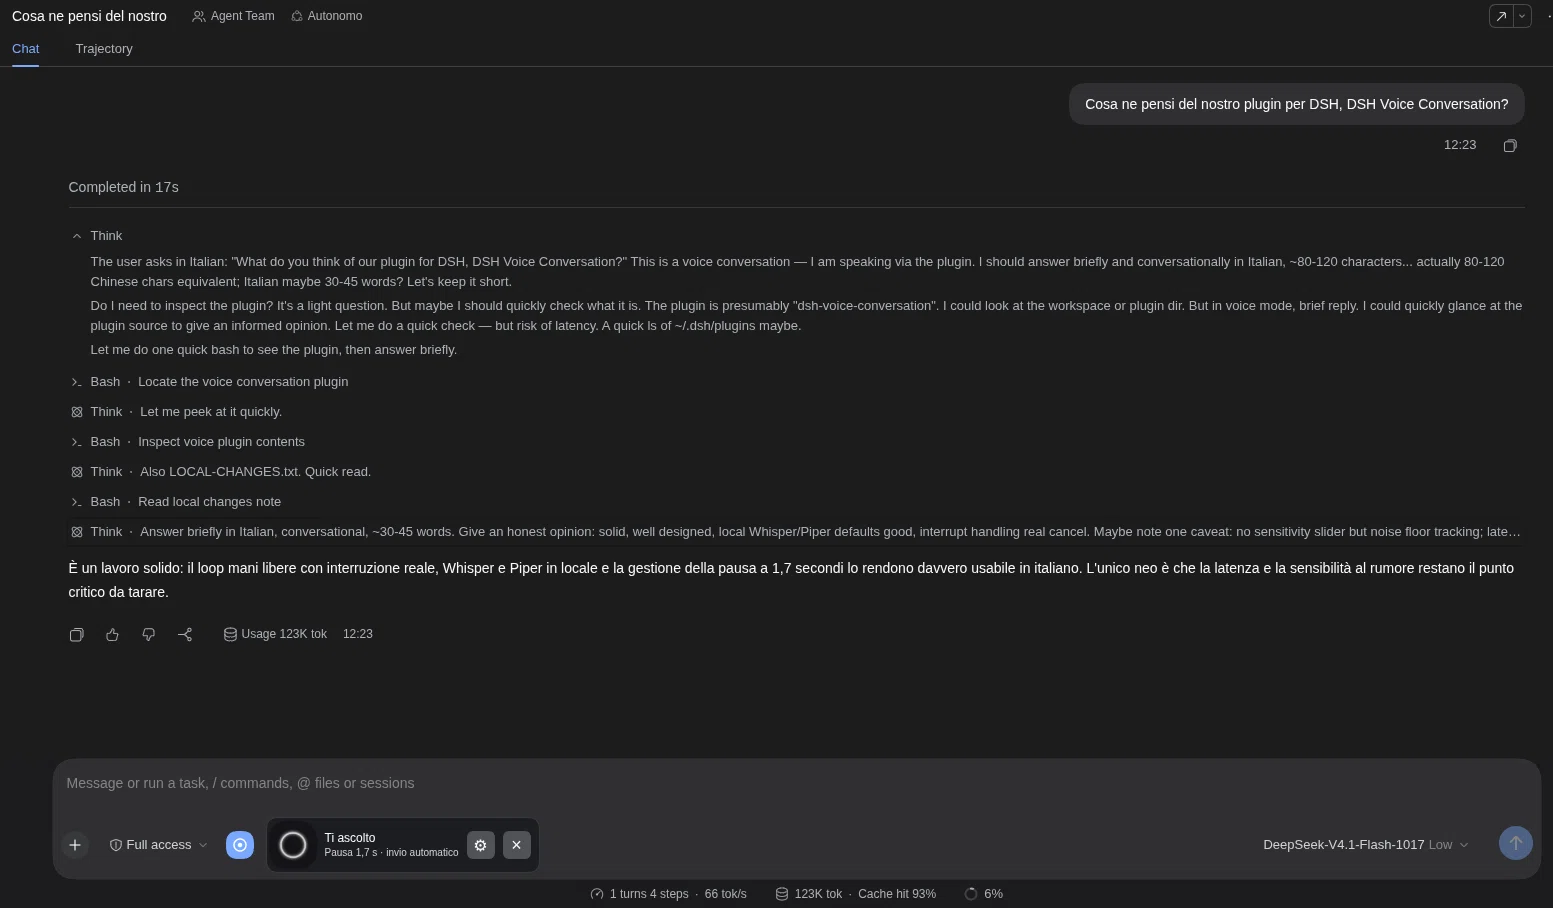
Maintainer / autore del fork: RedHunt07 · License: MIT. Original Voice Loop code by ZG2017; see NOTICE.md. Hands-free Italian/English conversations for DSH. Speak, pause for 1.7 seconds, and your prompt is submitted. After the final spoken reply, listening resumes using the same microphone stream. A compact composer dock keeps the native chat, tools and DSH-provided Think output visible. This displays reasoning exposed by DSH, not private model reasoning.
Guida italiana · npm package · GitHub Package · Credits and licenses
Compatibility
Tested: DSH 0.2.0-rc.2, Node.js 22+, Linux web profile. Other DSH releases, operating systems and browsers need validation. Microphone access requires localhost or HTTPS and browser permission. Use headphones to reduce loudspeaker echo triggering spoken interruption.
Install
npm package: dsh-voice-conversation (release 0.1.2).
dsh plugin --profile web add dsh-voice-conversation
This installs the current npm release. To pin the verified version:
dsh plugin --profile web add dsh-voice-conversation@0.1.2
The previous 0.1.1 release is also available as a prebuilt archive below.
# equivalent prebuilt GitHub archive
dsh plugin --profile web add https://raw.githubusercontent.com/redhunt07/dsh-voice-conversation/main/dist/dsh-voice-conversation-0.1.1.tgz
The DSH command also selects the bundle. Verify that "dsh-voice-conversation" occurs once in dsh.profile.bundles in $DSH_HOME/profiles/web/package.json (normally ~/.dsh/profiles/web/package.json); add it only if missing and preserve existing entries. Disable any older Voice Loop bundle first: the two plugins use the same API paths and cannot run together. Restart DSH and hard-refresh the browser.
No backend, global transcript preferences or background services are installed automatically.
Optional local backend
Extract the source archive and open its directory. Prerequisites: python3, uv, and ffmpeg on PATH. Setup creates an isolated Python 3.12 environment, downloading the interpreter through uv if necessary, and downloads approximately 3.1 GB of pinned Whisper/Piper model files. Review NOTICE.md first.
python3 scripts/runtime.py setup --device cpu
python3 scripts/runtime.py start
Whisper large-v3 can be slow on CPU. On Linux with a compatible NVIDIA CUDA 12 driver and sufficient VRAM (tested on a 16 GB GPU), use setup --device cuda instead. Setup installs pinned CUDA libraries inside its environment, not system drivers or system packages.
Keep the foreground process running; Ctrl+C stops it. Data lives at ~/.local/share/dsh-voice-conversation; --data-dir PATH overrides it. Whisper uses the standard Hugging Face cache. Inspect configuration and service availability with:
python3 scripts/runtime.py doctor
The backend binds only to 127.0.0.1:8766. DSH must run on the same machine; its host proxies the audio. Browser-origin requests are rejected. Local processes can access this unauthenticated backend; keep the port private. For remote browser access, DSH still needs HTTPS for microphone permissions.
Use and configure
Enable Voice Mode once in a DSH chat and allow the microphone. Select local recognition/synthesis. Choose paola for Italian speech or lessac for English. Recognition automatically chooses between Italian and English; output uses the selected voice and does not automatically switch language.
The dock shows listening, processing and speaking. Responses are read only after the agent finishes; intermediate tool-step text is skipped. Speak over a reply to interrupt it. Approval requests remain in the normal chat and can require a click. Close Voice Mode to release the microphone.
The default endpoints are http://127.0.0.1:8766/v1/audio/transcriptions and /v1/audio/speech. The local/cloud selectors are two configurable slots; both initially point to localhost. Configure compatible remote endpoints and credentials explicitly in plugin settings if desired. There is no implicit remote fallback or ambient API-key lookup. STT accepts multipart file and model, returns JSON {text}. TTS accepts JSON {model,input,voice,lang_code,response_format:"mp3"}, returns MP3 bytes.
Native Think sections open once while voice mode is active; manual collapse is respected. For more activity detail, optionally choose verbose transcript and detailed usage in DSH's own settings. The plugin does not override these global preferences.
Privacy and limits
更多「语音」插件
vox-director
作者 alisa0808
将主题自动生成 Vox 拼贴风解说或广告视频的智能体技能,全流程在 Atlas Cloud 与 ffmpeg 上自动完成。
dsh-voice-ai-girlfriend
作者 beiyege-01
语音 AI 女友(Voice AI girlfriend for DeepSeek Harness):Whisper 语音输入 + Qwen3-TTS 声音克隆 + 句子级流式朗读 + 数字人动画窗。插话/排队双模式,说话即打断。
dsh-voice-prompt-enhancer
作者 fishsb
DeepSeek-Harness (DSH) 插件:✨ 提示词一键增强(5 模式·模型链·记忆链)+ 💬 语音输入增强(热键·说完自动停·口水词清理·语音纠错)
dsh-plugin-tts
作者 1624318455
Edge TTS 语音朗读插件:朗读回复、自动朗读开关,免费无需 API key