
README

AI argues. Code settles. The losses stay on the page.



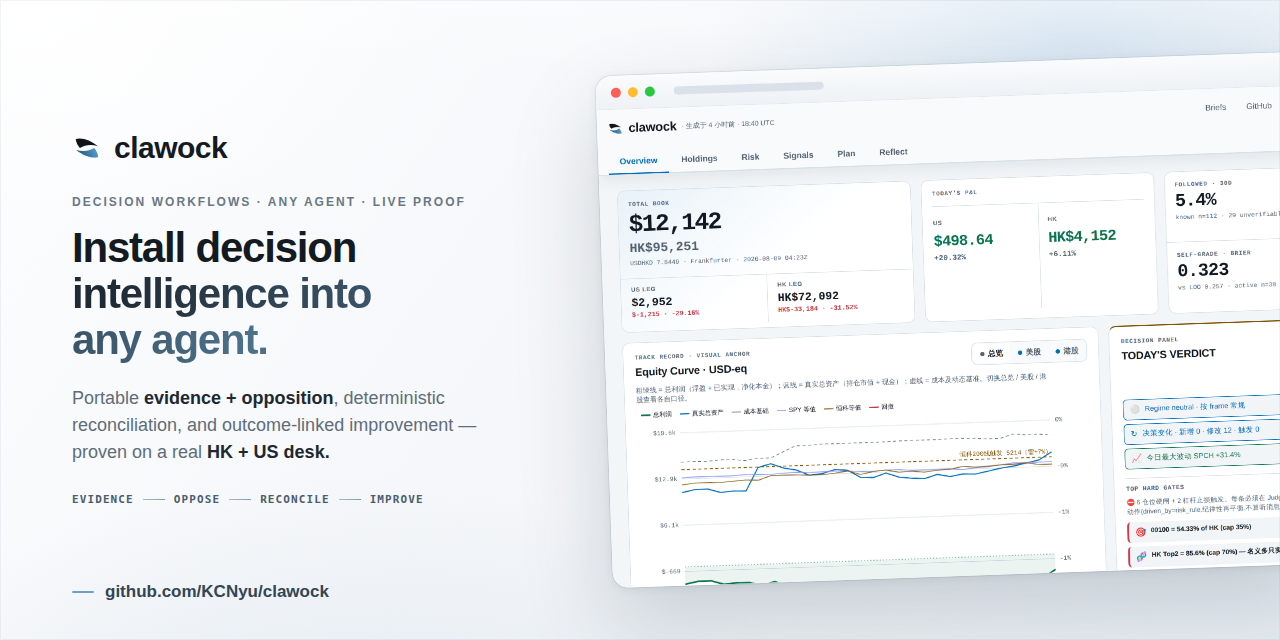
Live dashboard · Daily briefs · Evidence · 简体中文
“The market doesn't care how confident the model was.”
| 127 | 881 | 144 | 43 | 5 | 0 |
|---|---|---|---|---|---|
| days live on a real HK + US account | decisions on the public ledger | episodes settled by code | data modules across 8 layers | agent harnesses, one contract | scores the model wrote for itself |
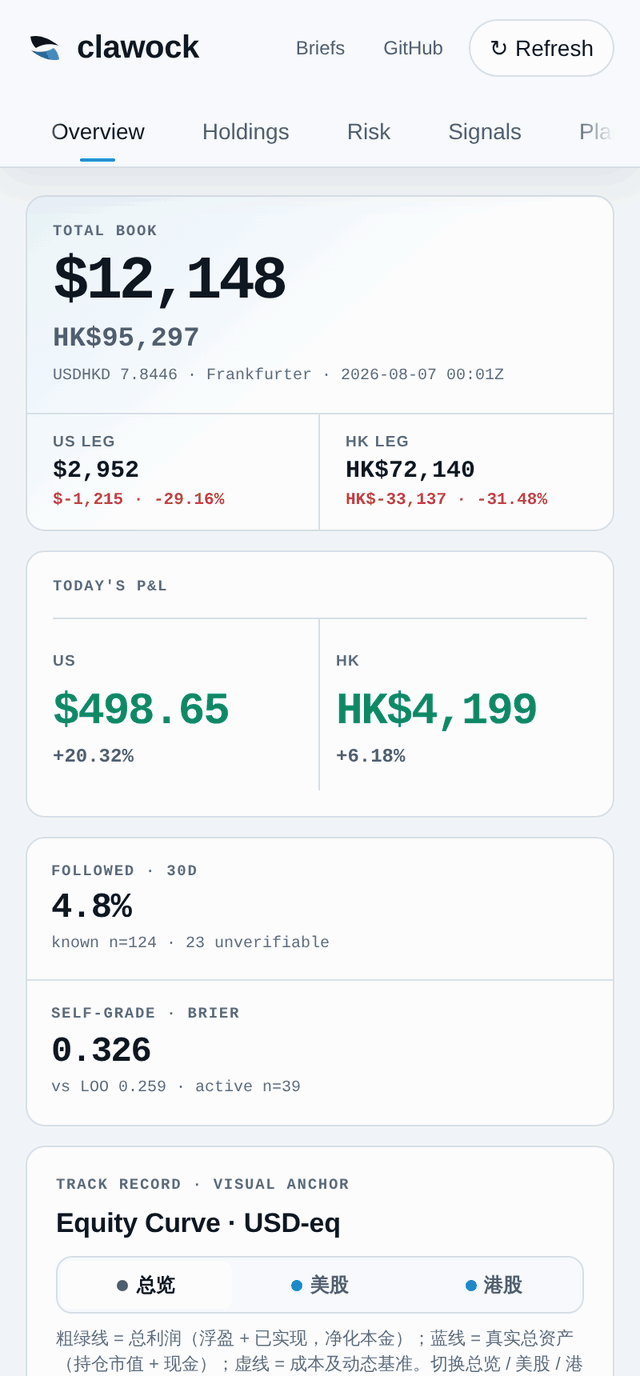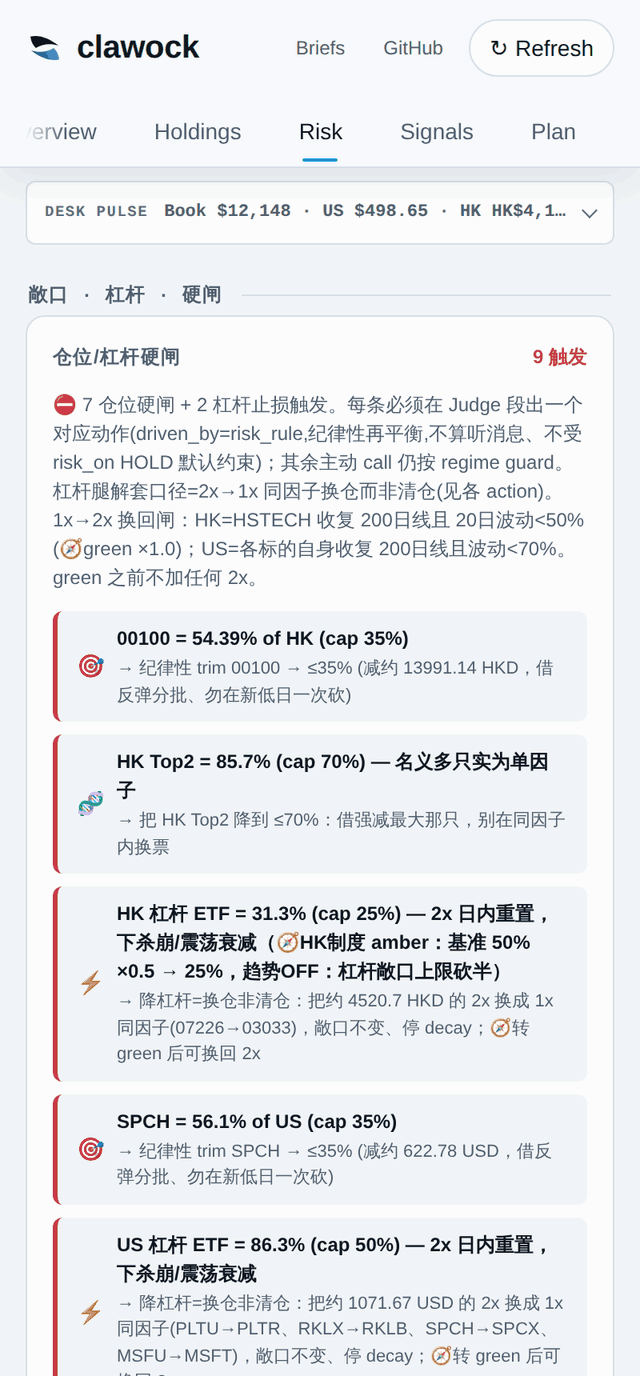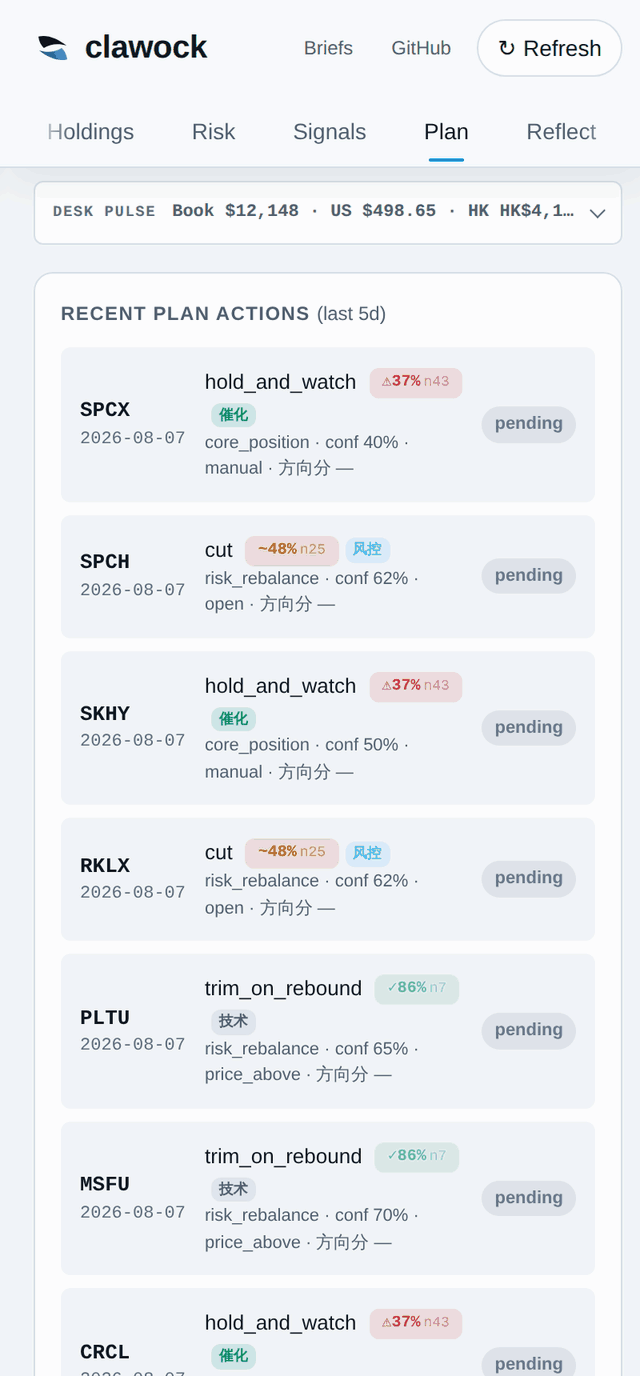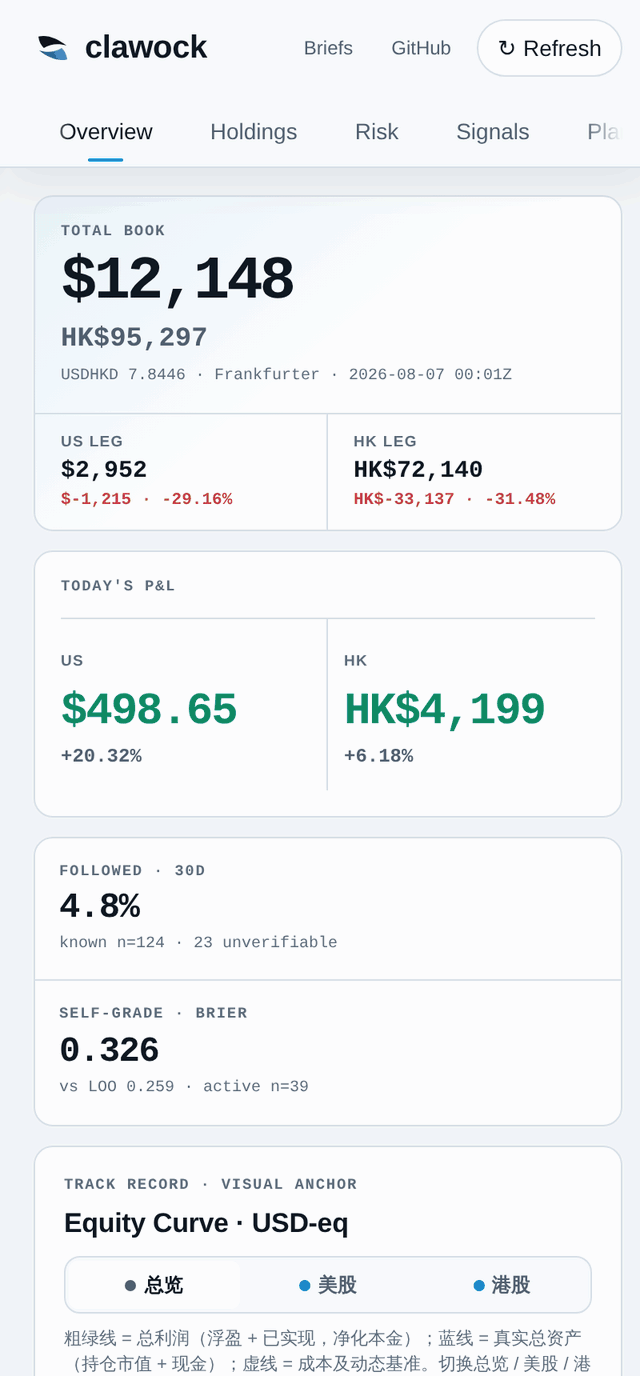
Real positions, real P&L — −17.30% since day one, published exactly as it is — graded in the open. Numbers and previews refresh weekly; the live dashboard updates through the trading day.
Every trading day, clawock turns raw market information into decisions that get graded:
- Collect. 43 fetch and compute modules across 8 layers: quotes, SEC and HKEX filings, capital flow, bilingual news, Reddit and influencer feeds, with multi-source fallback. Python fetches; the model only reads the assembled context.
- Compute factors. Quant factors, cross-sectional ranks, peer residuals and a trend × volatility leverage dial, all computed deterministically in Python.
- Backtest. A factor's clustered bootstrap interval has to clear 50% before it may influence a decision; the cross-sectional layer is pre-registered; the leverage dial is scored out of sample. What fails is published on the evidence page.
- Decide. Four analyst lenses, a bull and a bear, three risk voices and a judge argue over the same context and write
plan.json. - Settle. Python settles every decision against real prices. The model never touches its own score, and every result lands on the public scorecard.
The whole pipeline plugs into the agent you already use: Claude Code, Codex, OpenClaw, DeepSeek Harness, or your own → install and the full loop
What this is
This started as one account, not a package. A multi-agent desk debates the evidence on a real brokerage account with separate Hong Kong and US books and proposes trades; the account owner still places the orders. What comes out of that is the record: real positions, a growing decision history, and a public scorecard the model has no say in — not a get-rich bot, and not a copy-trading service.
clawock is the part of that desk pulled out to be reusable. Your runtime keeps
the model call, the conversation, memory, tools, permissions and credentials.
clawock adds the decision contract on top: certified evidence, a required
opposing case, checked money and FX arithmetic, and outcomes linked back to the
decision that caused them. It is files and a CLI, so switching harness leaves
the contract unchanged.
examples/ runs the
same decision from a pure CLI, an OpenClaw skill, a Claude Code instruction, a
Codex AGENTS.md, and a DeepSeek Harness agent.
To try it without installing anything locally, open a Codespace and run
examples/cli/minimal-run/run.sh: a clean virtualenv, no credentials, no
broker, and the same script CI runs against every published wheel.

What makes it different
- A workflow plugin, not another agent or harness. The runtime keeps its model, chat, memory, skills engine, tool loop and permissions; clawock owns only the decision contract, so it moves between runtimes unchanged.
- The loop continues after the answer. Evidence, the opposing case, thesis, decision, execution, and observed outcome share one lineage. Measured results can propose bounded parameter changes, but never silently rewrite strategy.
- Real money, graded in public. One live Hong Kong + US brokerage account, with a public scorecard that keeps every eligible result — the losses included, and the fact that the active calls haven't beaten buy-and-hold. Each published headline names the ledger slice, window and commit it was computed from, and
clawock scorecard-provenance --checkrecomputes it frommemory/decisions.jsonl— a re-graded row inside a published window shows up as a mismatch. - The model can't grade itself. LLMs propose trades; Python settles them and computes the scorecard.
- One thesis, one episode. Repeated opinions on the same thesis count once. Each episode is settled from canonical vendor bars, with declared gap-fill rules when a session is missing.
- The ledger has to reconcile. A money-conservation check runs before every push; if cash, positions, and P&L don't balance, nothing is published.
- Built to keep running. Scheduled Hong Kong and US sessions produce the daily briefs and refresh the live dashboard through the trading day.
For the canonical EN/ZH rendering of every project term — composite, regime, DSR, CSCV, triple barrier, run card and the rest — see the glossary.
How it works
The product boundary is simple: the external agent reads and reasons; clawock owns the portable decision workflow and the deterministic truth around it.

The KCNyu deployment then applies that product boundary to one live portfolio. This second diagram is the deployed KCNyu desk, not the reusable package boundary.

Every trading day the system pulls fresh prices, FX, volatility, earnings and macro context plus news and social sentiment; hands that normalized context to a multi-agent debate; applies deterministic risk, schema, and ledger gates in Python; delivers a brief to WeChat; and updates the public dashboard.
The information layer
Reading the market is most of what the LLM does, so the widest part of the system is data collection. The repository catalogs 43 fetch and compute modules across 8 layers, with bilingual Hong Kong + US coverage — live quotes, SEC + Eastmoney filings, capital flow, earnings calendars, macro (VIX / DXY / 10Y), Reddit and news sentiment, and market-moving social feeds. Each brief consumes the subset relevant to that market and session. Collection stays broad; the decision layer stays constrained.
Coverage is bilingual, but it is not symmetric, and the asymmetry is in research breadth rather than in the basics. Quotes, fundamentals, news and cash-flow reconciliation all have real Hong Kong branches. Two research-breadth capabilities do not: same-industry peers are discovered automatically for US names and read from a curated map for Hong Kong ones (peer_discovery.py — the mechanism is verified, the flag stays off until the peer-residual rules are re-registered against the wider universe), and US trading halts arrive as a structured feed while a Hong Kong suspension arrives as an announcement that the triage rules mark for a human (mover_evidence.py). So: Hong Kong base coverage on par, Hong Kong research breadth behind US.

All 8 layers, row by row — modules and primary sources
| Layer | Modules | Primary sources |
|---|---|---|
| 1 · Market | 7 | Tencent · Yahoo · Eastmoney · Polygon |
| 2 · Fundamentals & filings | 3 | SEC EDGAR · Eastmoney datacenter · HKEX |
| 3 · Capital flow | 1 | Eastmoney push2his |
| 4 · News & catalysts (bilingual) | 5 | Eastmoney · Finnhub · Google News · exchange filings |
| 5 · Macro & sentiment | 3 | Yahoo · Reddit · CNN · social feeds |
| 6 · Quant & risk | 9 | deterministic math over price history |
| 7 · Book & FX integrity | 6 | Frankfurter · the reconciliation ledger · local invariants |
| 8 · Backtest & calibration | 9 | local snapshots + canonical bars |
The fetch layer degrades gracefully: every live Eastmoney call routes through one throttled gateway, critical paths (quotes, FX) use multi-source fallback, and an empty fetch keeps the prior value instead of overwriting a good series with a blank. Public sources include Tencent, stooq, yfinance, Frankfurter, SEC EDGAR, Finnhub, Nasdaq, Eastmoney, Polygon, Alpha Vantage, Reddit, and Google News — full command and provider catalog in the command reference, whose inventory is generated from the same registries this table is checked against. Which module sits in which layer is itself an artifact — config/information-layers.json, where every packaged command is either in a layer or listed with the reason it is not collection — and CI checks the table above against it, so a module that moves cannot leave its count standing.
What each run actually receives
Collection is broad, but no run gets everything. Each scheduled job's preflight assembles only the blocks that job can act on, writes them to a context file, and the model reads that file rather than fetching for itself.
sources
  ──► preflight (Python, deterministic)
  ──► context.json
  ──► LLM prose
  ──► postflight (Python)
  ──► publish
Pre-open gets the most: full position truth, risk, signals, the evidence graph, research state, and it writes the day's plan. The open/midday/close runs travel light — a fresh quote, risk only when signals demand it. Intraday check-ins (every 30 minutes a market is open) sit in between: more signal detail, but no research production and no evidence-graph rebuild, because that is a daily artifact and would be stale by construction.
The full block breakdown — row by row, by cadence
| Pre-open brief | Open / midday / afternoon / close | Intraday check-in | |
|---|---|---|---|
| When | 08:03 HKT, weekdays | HK 09:30 · 12:00 · 13:30 · 16:00 · US open and close | every 30 min while a market is open |
| Blocks | 40 | 17 | 31 |
| Position truth | holdings, book totals, concentration, leverage look-through | fresh quote block | fresh quote block |
| Risk | guardrail, discipline ledger, β/vol/drawdown, breakeven math | risk section only when signals demand it | signal counts and detail |
| Signals | quant factors and their hit-rate review, cross-sectional factor, peer residual, T+0 setups, the close-confirmed opportunity radar (which names closed above their prior 20-day high, and why an empty add side is empty) | peer/sector scan | peer/sector scan, T+0 setups, anomaly flags, entry setups and early-trend candidates re-run on the open bar, price-surface opportunity radar |
| News and events | evidence graph, Chinese-language company news, catalyst calendar, macro, Reddit and social feeds | catalyst probe on flagged names | catalyst probe on flagged names |
| Research state | thesis registry, research work queue (reviews due, overdue promises, ungated positions) | thesis and red lines for flagged names | thesis and red lines for flagged names |
| History | retrospective, decision metrics, reflections, data-integrity report | — | heartbeat slot state |
| Today's plan | writes it | the morning's still-open decisions for this leg, and which of their trigger prices the current quote already satisfies | the morning's still-open decisions for this leg, and which of their trigger prices the current quote already satisfies — checked arithmetically and printed in the block, not left for the model to notice |
Block counts are the top-level context sections each cadence emits, pinned by CI (tests/test_readme_parity.py) against the preflights' own context dicts — packet-identifying envelope keys (context_id / generation_id) are not counted, which is why a written artifact carries one key more than this number.
The catalyst probe is the narrow, time-sensitive one: it fires only for names that already moved, reads exchange and regulator filings first (SEC acceptance timestamps, HKEX announcements), classifies each item as interrupt, context or noise, and states no_recent_filing explicitly rather than letting an empty block read as "nothing happened".
Influencer radar
The system scans eight sources across US and HK twice every trading day over a rolling 48-hour lookback window: Trump (Truth Social, first-party), Musk (news aggregation), Cathie Wood / ARK Invest (their published daily trades — ticker, direction, share count, ETF weight), Serenity (public Substack posts), and four media-proxied figures with no fetchable first-party feed — 段永平, 洪灏 (HK media), Michael Burry and Pelosi (congressional disclosures). An LLM then filters the noise and links what's left to actual holdings and sectors: stance (endorse / oppose), relevance, and a plain-language summary. Who said what, and whether it touches your book, is already sitting in the pre-open brief — nobody has to go scroll social media for it.
Each source carries its own candidate budget, so no single loud feed (Trump can post dozens of times a day) can crowd the others out of the LLM batch. What each source is and how fresh it is (a first-party post, a news proxy, a disclosed trade from 30–45 days ago) is kept per item and shown in the dashboard card.
A concrete example: in the scan of 2026-08-17 21:54 UTC, five Musk/SpaceX posts all matched real holdings (held_hits=5, the SPCH/SPCX cluster), and the next morning's brief carried it verbatim — 撞持仓 (5 条全中 SPCH/SPCX). The scan the following day's brief quotes (2026-08-18 21:52 UTC) found 1 post and zero holding hits — an empty result is published as an empty result, not skipped. Both entries can be checked against the published briefs of those two days. Misses go in the brief exactly as often as they happen.
How it decides
Analysis resolves into explicit, gated strategy decisions — and one stock can carry several at once.
- Several strategies, graded separately.
core_position,risk_rebalance,intraday_t,event_trade, andtactical_entrycan coexist on the same name, because a long-term thesis and an intraday trade can legitimately disagree. Each is graded in its own episode. - Attribution-first. Every decision is tagged by its dominant driver, and that driver's edge is measured dynamically from the record — no hit rate is hard-coded into the logic.
Low-frequency add campaigns
Adding to a position needs two independent evidence families to agree: price-relative (factor rank plus curated-peer residual), point-in-time news (reliable positive surprise or accelerating attention), or a confirmed un-overheated 20-day breakout — not one moving average mistaken for alpha. Any two families authorise a capped exploration slice; validated authority still requires decision-usable evidence on both the price and the information side, so a price pattern can never promote a leveraged name. Negative information or peer-laggard evidence blocks it outright, sizing stays capped and tranche-based (a warming policy earns a small exploration slice, not validated authority), and a small rank wobble can't churn permission off and on.
- Falsify, don't confirm. In a risk-on tape the default is HOLD. A bullish story doesn't trigger a buy until it clears a disconfirming check and an "is this already priced in?" test on the last few days' move.
- Regime over timing. Leverage isn't timed; a 200-day-trend × volatility dial sets the cap. The backtested lesson: the edge was in de-leveraging in the wrong regime, not in calling tops.
The debate
The daily deep brief runs a structured multi-agent debate, adapted from TradingAgents for separate Hong Kong and US books. More agents isn't the point: the protocol demands an opposing case, and the Judge attributes each resolution to a named strategy frame.

- Analyst lenses. Fundamental, technical, sentiment, and sector-rotation agents read the same context and merge into one table. Every claim must cite numeric context.
- Bull vs Bear. Two researchers build opposing cases, each citing concrete analyst data points. The protocol asks them to genuinely disagree on at least one position and to record it, so unanimous agreement reads as a flag rather than evidence.
- Devil's advocate. The Bear researcher is assigned to name and attack the session's strongest consensus view — never the weakest — so a lopsided bull tape cannot go unchallenged by cherry-picking, and the attack it lands is written down.
- Risk voices + a Judge. Aggressive, Conservative, and Neutral each argue their corner; the first-mover voice rotates every four trading days so the framing cannot calcify. A Judge weighs them, names the strategy frame driving each decision, and resolves the argument into
plan.json— which enters the next session's grading pipeline.
The public scorecard
Every call is settled mechanically and published — wins, losses, and the cases that can't be graded. Nothing is hand-tuned after the fact.
- Record — the model submits a versioned decision with its strategy, condition, regime, size, and confidence. The authoritative ledger is
memory/decisions.jsonl. - Trigger — Python evaluates it against canonical unadjusted daily bars, counted on each market's own calendar. An unfinished session grades nothing, and a gap straight through a trigger fills at the open — never at a price that was never available.
- Group — repeated calls of the same strategy collapse into one episode, so holding a position for five mornings does not manufacture five samples.
- Grade & publish — code settles the outcome, scores it against a plain directional baseline, and renders it. Shut sessions, calls that need human evidence, and instruments that didn't trade are published as ungradeable — out of the win-rate denominator, but kept visible in the coverage count instead of silently dropped.
The model submits decisions; it can never write or amend its own evaluation. That isolation stops the desk from grading itself — it does not make the market data or the metric definitions correct. Treat the record as a diagnostic, not as proof of return.
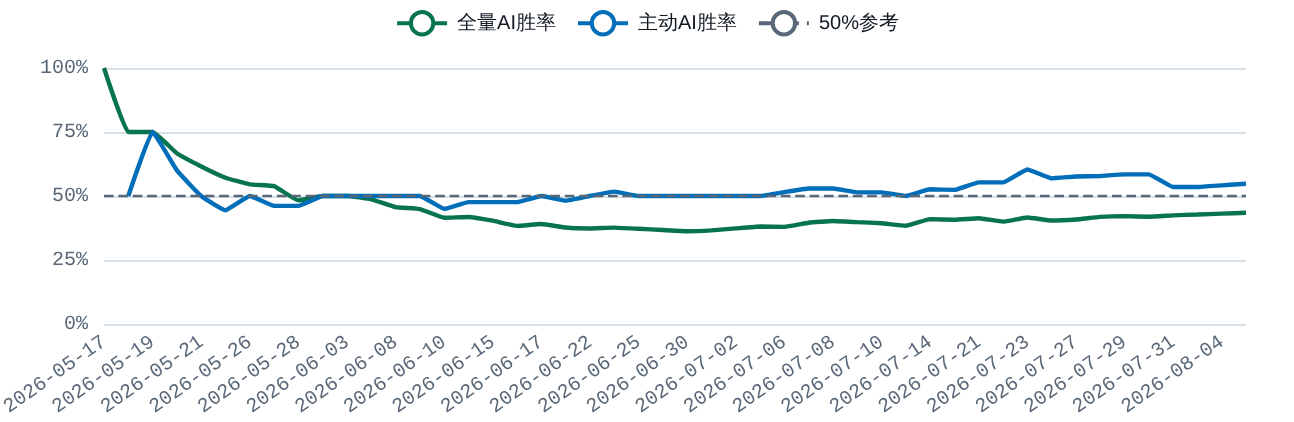
Cumulative episode win rate against a 50% directional-hit line — how often the direction was right, not what it earned. The buy-and-hold comparison is the Shadow Portfolio under Holdings; this is a different question. Refreshed weekly by GitHub Actions; live figures are on the Holdings tab.
How the grading handles the hard cases
- Incomplete sessions & missing bars. Triggers and marks come from
memory/bars/— unadjusted daily bars from a single canonical vendor feed, not an exchange feed. An unfinished session never grades anything. - Reaffirmations. Consecutive restatements of the same strategy/action are one episode. Re-anchoring a trigger to where the stock has since moved is still a reaffirmation, not a new call.
- Episode aggregation. An episode scores as the mean of its own settled calls, not an elected member — letting the first or last call speak for the group can swing the active win rate across the 50% line on nothing but that choice.
- Confidence calibration. Stated confidence remains an audit field. A strictly prequential beta-binomial hierarchy estimates action × driver × condition × regime probabilities from earlier dates only, shrinks sparse groups toward broader priors, and abstains from signal sizing when evidence or the posterior lower bound is insufficient.
- Timing, priced separately. A single-event diagnostic asks how much better or worse the trigger fill was than that session's close, strictly paired by ticker/date/direction/shares. It deliberately never draws a cumulative money curve.
- Shadow portfolio (simulated · not live). Two cash + inventory books replay the same timeline: one follows every triggered active call, the other buys and holds. Their cumulative difference is reported as simulated timing alpha, gross — fills are
qty x price, so it carries no commission and no spread. A net figure is published beside it, never instead of it: the same replay with a pre-registered haircut deducted at each fill (config/cost-model.json), whose assumptions ride in the payload with every number they moved. They are assumptions, not observations — nothing here reads a broker invoice — and market impact is deliberately not modelled. It keeps USD and HKD separate, exposes how few calls were ever actually executed, and discloses the unadjusted-bar bias. Source:assets/data/shadow_portfolio.json. It is a policy simulation, not a claim about what the live account earned.
What we tested, and what failed
更多「Agent、自動化與工作流程」外掛
archify
作者 tt-a1i
為編碼智慧體生成美觀可驗證的架構圖、時序圖與資料流圖,輸出自包含 HTML,支援動效與清晰匯出。
openviking
作者 volcengine
為 AI 智慧體打造的自進化上下文資料庫,統一智慧體記憶、知識 RAG 與技能。
nocobase
作者 nocobase
開源的 AI + 無程式碼應用搭建平臺:AI 在久經生產驗證的底層基礎設施與所見即所得的無程式碼介面之上工作,幫你快速構建 CRM、ERP 等業務系統,兼顧速度與可靠性。
learn-harness-engineering
作者 walkinglabs
Harness 工程新手教程,從 0 到 1 系統學習智慧體工作流框架。